Long Read Sequencing Market Size, Share, Trends and Forecast, 2026–2034
REPORT DETAILS
Long Read Sequencing Market Summary
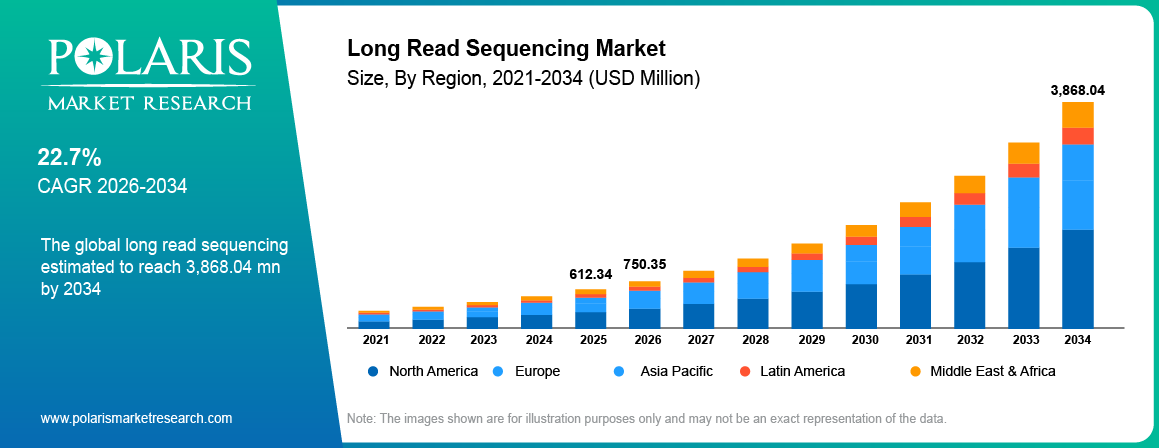
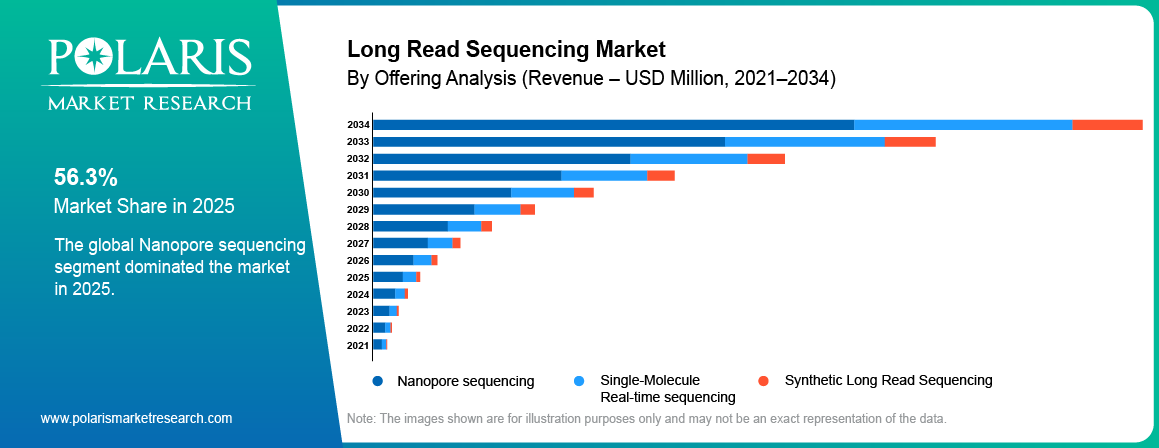
Long read sequencing market size was valued at USD 612.34 million in 2025 and is projected to register a CAGR of 22.7% during 2026–2034. Growth is driven by lower per-genome costs, a shift to clinical genomics, and technological advances.
Market Statistics
Key Takeaways
- The North America market dominated with the largest share of 51.9% in 2025, led by high investments in genomic research and advanced healthcare infrastructure.
- As per our long read sequencing market forecast 2034, Asia Pacific market is expected to witness the highest CAGR of 25.4% during 2026–2034. The growth is driven by growing investments in biotech and increasing research activities.
- The European market is expected to register a CAGR of 21.8% during the projected period. It is driven by rising interest in genomic research, government funding, and a growing focus on personalized medicine.
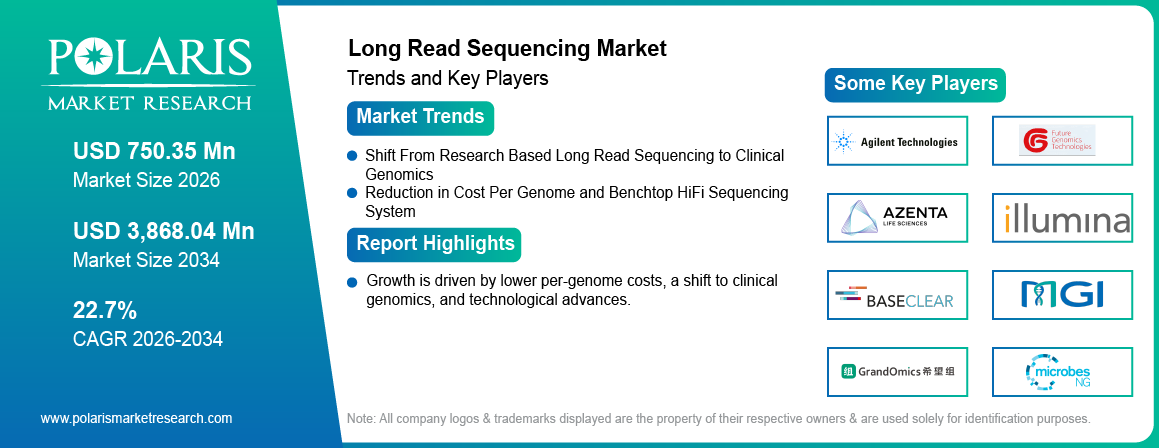
- Nanopore sequencing dominated the long read sequencing market share with 56.3% in 2025. Nanopore sequencing is in demand due to the ability of the technology to provide real-time analysis of long DNA or RNA strands.
- The instruments segment is expected to witness a CAGR of 21.2% during the forecast period, driven by growing demand for advanced sequencing systems that deliver accurate and reliable results.
Note: Figures and projections outlined in this report are the result of Polaris Market Research’s proprietary analytical processes, grounded in the latest available datasets and market observations.
What is Long Read Sequencing?
Long-read sequencing refers to a group of DNA and RNA sequencing technologies. It reads individual molecules spanning thousands to hundreds of thousands of bases in a single pass, and more than a megabase in some nanopore workflows. The longer reads allow for laboratories to resolve complex genomic regions with far fewer overlapping fragments than short-read methods.
In simple terms, genome sequencing is like rebuilding a shredded book. However, short-read platforms cut the text into lines of 150-300 letters. This makes repeated passages and rearranged chapters hard to put back. Long reads retain whole pages, making repeats, structural variants, and haplotype phasing of each variant easily visible.
The technology is often called third-generation sequencing or single-molecule sequencing, although they are not necessarily synonyms. Two native single-molecule approaches are prevalent. PacBio's Single Molecule, Real-Time (SMRT) sequencing generates highly accurate HiFi reads through circular consensus. Oxford Nanopore sequencing measures changes in current as the DNA or RNA passes through a protein pore and enables real-time analysis, ultra-long reads, and direct readout of RNA. Synthetic or reconstructed approaches such as Illumina Complete Long Reads derive long-range information algorithmically from short-read data. Native workflows can also capture base modifications such as 5mC methylation in the same run, although some targeted, low-input, cDNA workflows still require amplification.
The long read sequencing market covers instruments, consumables such as flow cells, SMRT Cells and library-preparation kits, and sequencing and data-analysis services. Demand is shifting from academic genome assembly toward rare-disease diagnosis, cancer genomics, pharmacogenomics, transcriptomics and microbial surveillance. It is driven by benchtop HiFi systems, reduced per-genome costs, and AI-assisted basecalling. Clinical laboratories, pharmaceutical developers, and population-genomics programs are now the fastest-growing buyers, alongside established academic users.
Long Read Instruments by Deployment Model
| Instrument | Vendor | Deployment model | Positioning / notes |
| MinION | Oxford Nanopore | Portable (single flow cell) | Field, decentralized, educational and rapid sequencing |
| GridION | Oxford Nanopore | Benchtop, up to 5 MinION flow cells | Mid-scale labs running independent experiments |
| PromethION | Oxford Nanopore | Benchtop to high-throughput, up to 48 flow cells | Population-scale and large-genome projects |
| Vega | PacBio | Benchtop HiFi | Up to 90 Gb HiFi per run with SPRQ-Nx; 2- and 4-hour run options; ~USD 995 US list per run; input from 500 ng |
| Revio | PacBio | High-throughput HiFi | Large-scale human WGS; SPRQ-Nx chemistry; 5mC/5hmC/6mA calling |
Source: Polaris Market Research Analysis
How Does Long Read Sequencing Work?
Long read sequencing is a technology used to read long stretches of DNA or RNA in a single run. Unlike short read sequencing, it can capture longer genetic sequences without breaking them into many small pieces. This helps researchers identify genetic changes, complex DNA regions, and structural variations more accurately. The process involves preparing genetic material, placing it on a sequencing platform, and reading the sequence as data. The results help researchers study diseases, improve diagnosis, and support advances in biotechnology.
Long Read vs Short Read Sequencing
| Attribute | Long-Read (Native Single-Molecule) | Short-Read |
| Typical read length | HiFi typically 15–20 kb; nanopore from short reads to >1 Mb (ultra-long) | Roughly 50–300 bp |
| Per-base accuracy | HiFi consensus ~99.9% (Q30); nanopore accuracy depends on chemistry and basecaller | Typically >99.9% |
| Structural variants | Spanned directly by single reads | Inferred; many large or complex events missed |
| Repeats and repeat expansions | Spans most tandem repeats and segmental duplications | Limited in long or complex repeats |
| Haplotype phasing | Read-based phasing over long distances | Short-range or statistical |
| Methylation | Native detection from the same run (platform-dependent) | Needs bisulfite or enzymatic conversion |
| Throughput per run | Lower to moderate | Very high |
| Sample requirements | High-molecular-weight DNA preferred; input varies by protocol | Low input; tolerant of degraded DNA |
| Data and compute | Larger raw-signal files; specialized assembly and SV tools | Mature, standardized pipelines |
| Cost per genome | Higher, but falling with new chemistries | Lowest |
| Typical applications | Rare disease, SV discovery, de novo assembly, isoforms, PGx | Population WGS, exomes, panels, liquid biopsy |
Source: Polaris Market Research Analysis
Impact of AI on Market
- Artificial intelligence is used to improve DNA sequencing accuracy by reducing errors and producing more reliable genetic data.
- AI helps speed up sequencing data analysis by processing large datasets in less time.
- Systems with AI integration identify genetic variations by detecting complex changes linked to inherited diseases and cancer.
- It helps reduce analysis costs by automating data processing and limiting manual work.
- AI helps improve disease research by identifying genetic patterns and supporting a better understanding of diseases.
- Adoption of AI is expanding clinical applications by supporting rare disease diagnosis, precision medicine, and genetic testing.
Market Dynamics
Driver: Shift From Research Based Long Read Sequencing to Clinical Genomics
The increasing application of long read sequencing in clinical genomics propels the market growth. Researchers and healthcare organizations are adopting the sequencing technology and its applications to identify and understand genetic variants associated with hereditary diseases and complex disorders. The technology enables the researchers to recognize the genomic variations that could be missed out by the short-read sequencing technology. Moreover, as the clinical laboratories are embracing advanced genetic testing techniques the demand for long read sequencing technologies is anticipated to grow.
Driver: Reduction in Cost Per Genome and Benchtop HiFi Sequencing System
The decreasing cost of sequencing per genome is also anticipated to drive the long read sequencing technologies market during the forecast period. The new advancements in sequencing technologies are facilitating the researchers to extract accurate data with reduced long read sequencing cost per genome. Moreover, the emergence of benchtop HiFi sequencing systems is also a crucial factor influencing the long-read sequencing market. These systems ensure that even small-scale labs do not require investing in expensive and space-requiring equipment. Thus, these factors are projected to escalate the growth of the long read sequencing market.
Driver: Multiomic Output from Single Sequencing
Multiomic output from single sequencing is gaining substantial traction and is projected to contribute to the growth of the market. The long-read sequencing can offer insights into different areas of genomics. Based on the instruments and approaches, the sequencing can help recognize the genetic variants, analyze transcriptomes, and detect certain modifications to DNA and RNA molecules.
Restraint: Cost, DNA Quality and Bioinformatics Burden
The cost of sequencing equipment and data analysis, as well as the requirement for high-quality DNA, may restrain the growth of the long read sequencing services market. Moreover, the analysis of big data requires professionals and advanced software, which small healthcare facilities and academic labs may lack. These factors may limit the adoption of the technology and affect the market growth.
Opportunity: Targeted Long-Read Sequencing
The opportunity for long-read sequencing market growth lies in targeted sequencing, which allows the isolation of specific regions of DNA or RNA. The use of amplicon sequencing, sequencing capture, CRISPR enrichment, or adaptive sampling sequencing makes it possible to investigate only the necessary part of DNA, thus reducing costs and time. Moreover, the growing need for such targeted analyses will probably promote the use of long-read sequencing in various fields, including disease research, diagnostics, and therapeutics.
Trend: AI Assisted Basecalling, Consensus, and Variant Calling
One trend in long-read sequencing is the use of artificial intelligence-assisted basecalling, consensus, and variant calling. The use of such programs as DeepConsensus, Dorado, and MinKNOW allows to analyze raw data and obtain accurate results. For example, DeepConsensus utilizes deep learning technology to determine the most probable nucleotide sequence based on the multiple alignment of reads. Dorado basecaller enables modeling of signal data as DNA sequences, while MinKNOW bioinformatics software is used to control the sequencer and monitor the data. All three programs are used in the process of variant calling to obtain precise results.
PacBio HiFi vs Oxford Nanopore vs Synthetic Long Reads (Pacbio vs nanopore / hifi vs Nanopore)
| Attribute | PacBio (SMRT / HiFi) | Oxford Nanopore | Illumina Complete Long Reads |
| Approach | Native single molecule; circular consensus | Native single molecule; ionic-current signal through a nanopore | Synthetic/reconstructed long-range information from short reads |
| Read length | HiFi typically 15–20 kb | Short to ultra-long (megabase scale) | Not a single physical long read |
| Accuracy approach | Consensus HiFi, ~99.9% | Raw and duplex/consensus via Dorado basecalling | Short-read base accuracy |
| Real-time / adaptive | No in-run selection | Real-time analysis; adaptive sampling | No |
| Direct RNA | No (full-length cDNA, e.g., Kinnex) | Yes | No |
| Native base modifications | 5mC, 5hmC, 6mA with SPRQ-Nx on Revio/Vega | 5mC, 5hmC and RNA modifications (model-dependent) | Not native |
| Instruments | Revio (high-throughput), Vega (benchtop) | MinION, GridION, PromethION | NovaSeq-series instruments |
| Strengths | Variant-calling accuracy, repeat expansions, PGx, isoforms | Portability, ultra-long assembly, direct RNA, targeted enrichment in software | Uses existing short-read fleets; relatively low DNA input |
| Regulated-lab features | RUO; 21 CFR Part 11 audit controls added on Vega (2026) | RUO | RUO |
Source: Polaris Market Research Analysis
What Is HiFi Sequencing?
Pacific Biosciences (PacBio) introduced an innovative approach, known as HiFi sequencing, to long-read DNA sequencing, characterized by its remarkable accuracy. By reading each molecule of DNA dozens of times, HiFi’s approach allows for the creation of a consensus sequence which can be used to determine various genetic variants, regions of interest (ROI), and structural variations.
Ultra-Long Reads, Direct RNA, and Adaptive Sampling
Ultra-long reads are used to read lengthy DNA sequences that traditional long-read approaches cannot fully resolve. Additionally, sequencing of DNA molecules can be performed directly on RNA molecules, which allows for further transformations. Finally, adaptive sampling refers to the process where a sequencing run is altered or modified in order to select target DNA regions within the sequenced reference genome during a single run. Each method mentioned above can enable researchers to focus their efforts and resources on portions of a genome that can provide meaningful details in their fields of research.
Native Single-Molecule vs Synthetic/Complete Long Reads
These approaches can be used for deep genome exploration and sequencing. Firstly, native single-molecule long reads are built from single DNA or RNA molecules depending on the sequencing instruments and approaches, and can indicate variations and several epigenetic modifications for the sequenced region. The length, however, tends to be limited as most of these runs do not exceed ten million bases. Additionally, long reads utilize fragments of synthetic DNA, each about ten million bases in length. Lastly, the complete long reads, as the name implies, are designed to produce entirely single-read sequences that span from one end of a specified location to the other. Hence, variations of the technologies include unique variations and capabilities that each can utilize while genome sequencing.
Report Segmentation
By Technology Analysis
SMRT (Single-Molecule Real-Time Sequencing) is expected to witness a CAGR of 21.9% during the forecast period. This is due to the technology providing highly accurate long DNA reads, facilitating complex genetic variant discovery, and driving the study of disease inheritance. The increasing need for genome sequencing and personalized medicine is a significant factor driving the market for single-molecule real-time sequencing. Moreover, with the constant improvements in the accuracy and performance of sequencing, several academic institutions, clinical genomics laboratories, and biotechnology companies encourage the adoption of this technology.
Nanopore sequencing dominated the long read sequencing market share with 56.3% in 2025. Nanopore sequencing is in demand due to the ability of the technology to provide real-time analysis of long DNA or RNA strands. This sequencing method allows researchers to carry out genomic analysis in a laboratory and achieve remarkable results. Moreover, the growing need for analyzing pathogens and environmental DNA and continuous process improvements make nanopore sequencing even more attractive. These technologies are considered portable and are used in laboratories and field settings.
Synthetic long-read sequencing is expected to record a CAGR of 20.4% during the forecast period. The growing need to analyze complicated regions of the genome and the need for improved genome assembly drives the demand for synthetic long-read sequencing. This method allows the synthesis of long DNA molecules by combining short DNA strands with overlapping regions. Moreover, the use of this technology enables researchers to determine genetic variants that cannot be discovered using standard short-read sequencing. The increasing need for cost-effective genome analysis and extensive genetic studies is the primary factor influencing the demand for synthetic long-read sequencing.
By Offering Analysis
The instruments segment is expected to witness growth of CAGR 21.2% during the forecast period, driven by growing demand for advanced sequencing systems that deliver accurate and reliable results. Research laboratories, hospitals, and biotechnology companies are investing in long-read sequencing platforms to study complex genetic variations. Improvements in sequencing speed, automation, and data processing are also supporting adoption. The development of compact and user-friendly systems is making the technology more accessible to smaller laboratories.
The consumables segment dominated the largest share of 61.4% in 2025, driven by the recurring need for sequencing kits, reagents, flow cells, and sample preparation materials. These products are required for every sequencing run, creating a continuous source of demand. Growing research activities, increasing genetic testing, and rising use of long-read sequencing in drug development are supporting segment growth. Improvements in consumable performance are also helping laboratories achieve more reliable sequencing results.
The services segment is expected to witness a 24.1% CAGR during the forecast period as growing as laboratories seek external support for sequencing, data analysis, and interpretation. High equipment costs and the need for specialized skills encourage smaller organizations to outsource these activities. Service providers help researchers process complex genetic data and obtain meaningful results. Growing demand for genome analysis, clinical research, and drug development is expected to increase the use of long-read sequencing services.
By Application Analysis
The whole genome sequencing segment dominated with the largest share of 30.6% in 2025. Growing demand for comprehensive genetic analysis is driving the whole genome sequencing segment. Long-read sequencing helps researchers analyze entire genomes and identify complex genetic variations that may be missed by short-read methods. Increasing research into inherited diseases, cancer, and rare genetic conditions is supporting adoption. Rising investment in precision medicine and advances in sequencing accuracy are further driving demand for whole genome sequencing.
Tandem repeat sequencing is expected to witness a CAGR of 23.6% during the forecast period. The growing need to study genetic disorders is driving demand for tandem repeat sequencing. Long-read sequencing can span repetitive DNA regions that are difficult to analyze using traditional methods. This helps researchers identify repeat expansions linked to conditions such as Huntington’s disease and fragile X syndrome. Rising demand for genetic testing and improved disease diagnosis is supporting the tandem repeat expansion.
By Workflow
Pre-sequencing is expected to witness a CAGR of 22.2% during the forecast period. The pre-sequencing segment is driven by the need for reliable sample preparation and high-quality genetic material. Steps such as DNA extraction, quality assessment, and library preparation directly affect sequencing performance. Growing adoption of long-read sequencing is increasing demand for efficient preparation kits and automated laboratory solutions. Improvements in sample preparation methods are helping laboratories reduce errors, save time, and obtain more consistent results.
Sequencing dominated the long read sequencing market size with 62.7% in 2025. The sequencing segment is supported by rising demand for accurate genetic analysis and longer DNA reads. Research laboratories and healthcare organizations are adopting advanced sequencing platforms to identify complex genetic variations and study diseases. Improvements in sequencing speed, accuracy, and real-time data generation are supporting wider adoption. Growing applications in genome research, clinical studies, and biotechnology are further contributing to segment growth.
The data analysis segment is expected to witness a CAGR of 22.5% during the forecast period, fueled by the growing volume and complexity of long-read sequencing data, increasing demand for accurate genomic interpretation, and advancements in bioinformatics tools. Rising adoption of artificial intelligence and machine learning enhances variant detection, genome assembly, and structural variation analysis. Growing applications in precision medicine, cancer research, rare disease diagnosis, and clinical genomics further accelerate demand for advanced data analysis solutions.
By End Use
Academic research dominated with the largest market share of 47.5% in 2025. The academic research segment is supported by increasing research into genetics, genomics, and human diseases. Universities and research institutes use long-read sequencing to study complex genomes, identify genetic variations, and understand biological processes. Greater research funding and collaborations with biotechnology companies are encouraging adoption. The growing need for accurate genome assembly and advanced genetic analysis is further supporting demand for long-read sequencing technologies.
Clinical research is expected to record a CAGR of 24.8% during the forecast period. The clinical research segment growth is attributed to growing interest in using long-read sequencing to study genetic diseases and develop new treatments. Its ability to detect complex genetic changes helps researchers investigate disease causes and identify potential genomic biomarkers. Increasing investment in precision medicine and clinical studies is supporting adoption. Growing efforts to improve genetic testing and develop targeted therapies are expected to create further demand for long-read sequencing.
Hospitals and clinics would register a CAGR of 22.3% during the forecast period. It is accelerated by increasing demand for accurate diagnosis of genetic disorders, rare diseases, and cancer. The rising adoption of personalized medicine, improved genomic testing capabilities, and advancements in clinical sequencing technologies are encouraging healthcare providers to integrate long-read sequencing into diagnostic workflows. Its ability to identify complex genetic variations supports better disease characterization and informed treatment decisions.
The pharma and biotech entities segment is anticipated to record a CAGR of 23.1% during the forecast period. This is driven by increasing investments in drug discovery, genomic research, biomarker identification, and precision therapeutics. Long-read sequencing enables comprehensive analysis of complex genetic variations, supporting target identification and disease understanding. Expanding pharmaceutical research pipelines, growing demand for advanced molecular tools, and increasing applications in biologics development are further accelerating adoption across pharmaceutical and biotechnology companies.
Segmentation Summary
| Segment axis | Sub-segments | Leader | Primary demand driver |
| Technology | SMRT sequencing; Nanopore; Synthetic long-read | Nanopore sequencing Technology | Accuracy vs read length/portability trade-off |
| Offering | Instruments; Consumables; Services | Consumables | Recurring flow-cell, SMRT Cell and library-prep pull-through |
| Application | Whole Genome Sequencing, Identification & Fine Mapping of Structural Variation, Tandem Repeat Sequencing, Pseudogene Discrimination, Haplotype/Allele Phasing, Reproductive Genomics, Cancer, Viral & Microbial Sequencing, and Others. | Whole Genome Sequencing | Variant classes short reads miss |
| Workflow | Pre-sequencing; Sequencing; Data analysis | Sequencing | Instrument runs and chemistry upgrades |
| End use | Academic & research; Pharmaceutical & biotechnology companies; Clinical laboratories; Hospitals; Sequencing service providers | Academic & research | Genome projects now; clinical labs fastest |
Source: Polaris Market Research Analysis
Long Read Sequencing Applications and Use Cases
| Application area | Primary long-read use cases | Key variant/feature classes resolved | Representative examples and value |
| Rare disease and repeat-expansion diagnostics | Resolve previously unsolved rare-disease cases; detect pathogenic repeat expansions; phase compound heterozygous variants; identify complex rearrangements missed by short reads. | Short tandem repeat (STR) expansions, repeat interruptions/mosaicism, structural variants (SVs), copy-number variants (CNVs), inversions, mobile-element insertions, phased SNVs/indels. | LRS can uncover variants missed in prior rare-disease workups, with particular value for SVs, STR expansions, and parental-origin phasing. |
| Cancer genomics: SVs, CNVs, methylation and phasing | Characterize tumor architecture; link distant breakpoints; reconstruct complex haplotypes; distinguish inherited from somatic variation; profile epigenetic states in tumor/normal comparisons. | Balanced and unbalanced SVs, gene fusions, complex rearrangements, chromothripsis-like events, CNVs, allele-specific methylation, phased tumor mutations. | Long reads improve resolution of complex SVs and enable direct detection of DNA methylation, supporting integrated analysis of tumor genomic and epigenomic alterations. |
| Long-read pharmacogenomics and difficult genes | Assign complete pharmacogene haplotypes and star ()-allele diplotypes; resolve gene–pseudogene and highly homologous loci; detect structural haplotypes affecting drug metabolism. | Star alleles, phased SNVs/indels, gene duplications/deletions, hybrid genes, pseudogene-derived variants, tandem repeats, CNVs in homologous regions. | HiFi amplicon sequencing can directly resolve and phase complex loci such as CYP2D6 without assembly or inference, enabling ancestry-agnostic haplotype assignment and improved drug-response interpretation. |
| Long-read transcriptomics and direct RNA | Define full-length transcript structures; discover novel isoforms; detect fusion transcripts; quantify allele-specific expression; profile RNA modifications at transcript resolution. | Full-length isoforms, alternative splicing, fusion transcripts, allele-specific expression, RNA editing context, m6A and pseudouridine modifications. | Direct RNA sequencing supports transcript-resolved detection of RNA modifications such as m6A and pseudouridine, while long-read transcriptomics enables discovery of novel isoforms and complex transcript structures. |
| Microbial genomics, metagenomics and genome assembly | Assemble complete microbial genomes and plasmids; track outbreaks and strains; characterize antimicrobial-resistance contexts; resolve metagenomic species and strains; build pangenome and telomere-to-telomere references. | Complete plasmids, AMR genes and their genomic context, virulence factors, mobile genetic elements, strain-resolved metagenomes, structural variation, repetitive regions, full chromosomes/plasmids. | Long reads support de novo assembly, close-strain differentiation, complete plasmid reconstruction, and T2T assemblies by spanning repeat-rich and structurally complex regions. |
Source: Polaris Market Research Analysis
Clinical Adoption
The clinical adoption of long-read sequencing is gaining popularity in areas where short reads have proven insufficient, notably the characterization of repeat expansions, complex structural variant detection, phasing information, difficult-to-characterize pharmacogenes, and complete assemblies of microbial and plasmid genomes. While adoption is led by specialist genetics, oncology, and infectious-disease laboratories, its spread to other hospital settings is currently limited by high costs, complex workflows and bioinformatics pipelines, immature analytics, limited reimbursement, and the need for strong clinical-validation evidence.
Regional Insights
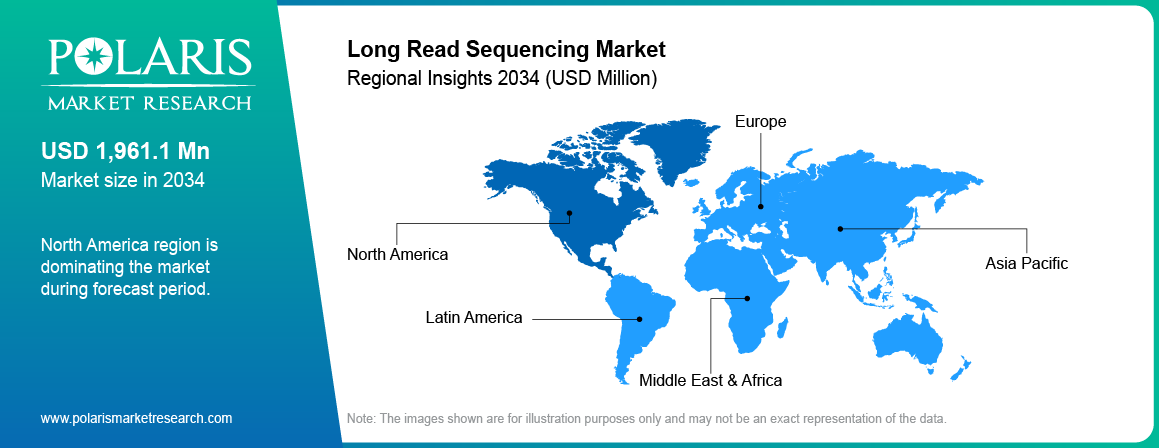
North America dominated with largest share of 51.9% in 2025. The growth of the North America long read sequencing market is led by high investment in genomic research and advanced healthcare infrastructure. The presence of key players such as Illumina, Pacific Biosciences and Oxford Nanopore Technologies further drives the growth. Demand for precision medicine and genetic disease research, as well as oncology studies, is fueling the need for long-read sequencing solutions. Government funding, academic research initiatives, and collaborations between biotech companies and research institutions are driving the growth of the market.
The Europe long read sequencing market is expected to witness growth of CAGR 21.8% during the long read sequencing market forecast 2034. The growth is attributed to rising interest in genomic research, government funding and a growing focus on personalized medicine. Countries such as the UK, Germany and France are prioritizing genetic research and advanced diagnostic technologies. Expansion of genome sequencing programs and collaborations between academic institutions, hospitals and biotechnology firms are fueling the market growth. Increased research on rare diseases, oncology and inherited genetic disorders are also contributing to the demand for long-read sequencing technologies across the region.
The Asia Pacific long read sequencing market is expected to witness long read sequencing market growth rate of 25.4% during the forecast period. This is owing to a growing investment in biotech and increased research activities. Rising government support and availability of advanced sequencing technologies are fueling market growth across the region. China’s focus on genomic research and biotechnology innovations is driving the demand for long-read sequencing solutions. Furthermore, a growing interest in cancer research, inherited diseases and precision medicine are also fueling the market growth. Japan is expected to see significant adoption due to the country’s focus on medical research and development of innovative precision medicine approaches. The rising need for genetic disease research and advanced diagnostic solutions are also fueling market growth. South Korea’s government backed initiatives in biotech and genomic research are promoting the use of long-read sequencing technologies. In addition, investments in personalized medicine and advanced healthcare technologies are creating additional demand for the technology. In India, increased investment in genomics, biotech and healthcare research are driving the market growth. Growing interest in rare disease research, genetic testing and cost-effective sequencing solutions are fueling the market growth.
The Latin America long read sequencing market is expected to record a CAGR of 21.3% during the forecast period. The growth is supported by an increase in biotech activities and rising interest in genetic testing solutions. Countries such as Brazil and Mexico are focusing on advancing their research capabilities and healthcare infrastructure. The rising demand for infectious disease research, oncology studies and genetic disorder analysis are driving the adoption of long-read sequencing technologies. Partnerships with global research organizations and access to genomic technologies are fueling the market growth in the region.
The Middle East and Africa long read sequencing market is expected to register a CAGR of 20.7% during the forecast period, due to increased investments in healthcare technologies and an increase in genomic research initiatives. In addition, rising awareness around inherited diseases and support for precision medicine and advanced healthcare technologies are fueling the growth of the market. In Africa, interest in infectious disease research and population genomics are creating opportunities for the long-read sequencing market. Enhanced government support, research collaborations, and improved laboratory infrastructure are expected to drive market growth across the region.
Regulation and Data Governance
Most long-read assays are currently research-use only; clinical assays are commonly developed as laboratory-developed tests (LDTs) within CLIA-certified laboratories, or require formal regulatory review as an IVD. In the U.S., an LDT is an IVD that is designed, manufactured, and used within a single CLIA-certified high-complexity laboratory. Commercialization of an in vitro diagnostic (IVD) product also requires electronic records and audit trail controls in accordance with 21 CFR Part 11; reimbursement typically requires evidence of clinical utility, and genomic data require appropriate informed-consent, de-identification, access-control, and privacy-protective frameworks
Competitive Insights
The long-read sequencing market is competitive, with key players focusing on technological innovation, sequencing accuracy, cost reduction, and wider applications. PacBio and Oxford Nanopore Technologies lead through their specialized long-read sequencing platforms. Illumina, MGI Tech, and other technology providers contribute through sequencing solutions and related products. Companies such as QIAGEN, Agilent Technologies, Twist Bioscience, and Takara Bio support sample preparation and research workflows. Service providers, including Novogene, BaseClear, and MicrobesNG, expand market access by offering sequencing and data analysis services to researchers and biotechnology companies.
Vendor Positioning: Long-Read Ecosystem by Business Model
| Role | Companies | Positioning |
| Native long-read platform vendors | PacBio; Oxford Nanopore Technologies | Instruments plus recurring consumables; define the core market |
| Adjacent / emerging platforms | Illumina (Complete Long Reads); MGI Tech (nanopore platform) | Synthetic or early-stage long-read offerings |
| Sample prep, enrichment and automation | Takara Bio; QIAGEN; New England Biolabs; Agilent; Sage Science; Twist Bioscience; Revvity; Hamilton; Tecan | HMW extraction, library prep, target enrichment and automated protocols |
| Sequencing service providers | BaseClear; Future Genomics Technologies (BaseClear and Leiden University collaboration); MicrobesNG; NextOmics; GrandOmics; Novogene; Azenta; CD Genomics; Daicel Arbor Biosciences | Outsourced long-read WGS, transcriptomics, microbial and hybrid sequencing |
| Academic / core facilities | Garvan Institute of Medical Research; Genome Transcriptome Facility of Bordeaux; I2BC | Research users and service cores; not instrument competitors |
| Clinical adopters (evidence generators) | Radboudumc; Maastricht UMC+; Greenwood Genetic Center | Clinical validation and LDT launches |
Source: Polaris Market Research Analysis
List of Long Read Sequencing Companies
- Agilent Technologies
- Azenta Life Sciences
- BaseClear B.V.
- Future Genomics Technologies B.V.
- GrandOmics
- Illumina, Inc.
- MGI Tech
- MicrobesNG
- New England Biolabs
- NextOmics
- Novogene Co., Ltd.
- Oxford Nanopore Technologies plc
- PacBio
- QIAGEN N.V.
- Revvity, Inc.
- Takara Bio, Inc.
- Twist Bioscience
Recent Developments
- August 2026, PacBio announced SPRQ-Nx chemistry for Vega: output up from 60 Gb to 90 Gb per run. U.S. list price per run cut from USD 1,100 to USD 995, 2- and 4-hour runs, 5hmC calling, input from 500 ng, and audit controls for regulated labs. Its shipping began in August. (Source: mlo-online.com)
- August 2026, Greenwood Genetic Center Diagnostic Laboratory launched standalone clinical long-read genome sequencing. (Source: ggc.org)
- March 2026, Daicel Arbor Biosciences launched the myReads long-read WGS service powered by PacBio HiFi. (Source: arborbiosci.com)
- February 2026, Radboudumc and Maastricht UMC+ reported a clinical comparison of long-read genome sequencing vs standard-of-care testing in 832 index cases (1,000 samples), showing 96.4% concordance and incremental diagnostic yield. (Source: pacb.com)
Future Outlook
The long-read sequencing market is expected to experience strong growth, driven by advancements in sequencing accuracy, declining costs, and increasing demand for precision medicine. Expanding applications in cancer research, rare disease diagnosis, genomics, and drug discovery will create significant opportunities. Asia-Pacific is anticipated to emerge as a key growth region, supported by research investments and healthcare infrastructure development. Integration of artificial intelligence and advanced bioinformatics will further enhance data analysis. However, high initial costs and technical complexities may challenge widespread adoption.
Research Methodology
- Market estimates are derived using a blend of primary and secondary research, validated through weighted-average and combined top-down/bottom-up modeling approaches.
- Secondary research covers company filings, genomics research publications, clinical trial registries, sequencing platform regulatory approvals, industry journals, and paid third-party databases to build baseline estimates.
- Primary research includes interviews with key industry participants such as sequencing platform developers, genomics service providers, bioinformatics specialists, and academic and clinical researchers, to validate accuracy and capture forward-looking insights.
- Base year considered is 2025, with a forecast provided through 2034; revenues are expressed in USD Million.
- Parent market is identified as the global DNA sequencing market; the addressable segment is narrowed using long read sequencing adoption rates across research, clinical, and pharmaceutical applications.
- Bottom-up model aggregates regional long read sequencing demand across technology, offering, application, workflow, and end use, validated against vendor revenue disclosures from Pacific Biosciences, Oxford Nanopore Technologies, Illumina, QIAGEN, Novogene, and others.
- Regional coverage spans North America, Europe, Asia Pacific, Middle East & Africa, and Latin America, further segmented by major countries.
- Projected 22.7% CAGR (2026–2034) reflects weighted analysis of improving read accuracy and declining sequencing costs, growing demand for structural variant and haplotype resolution, expanding clinical and cancer genomics applications, and increasing national genomics and population sequencing initiatives.
- Findings are cross-validated across multiple estimation methods to ensure consistency, accuracy, and reliability of the final market sizing.
Long Read Sequencing Market Segmentation
By Technology Outlook (Revenue – USD Million, 2021–2034)
- Single-Molecule Real-time sequencing
- Nanopore sequencing
- Synthetic Long Read Sequencing
By Offering Outlook (Revenue – USD Million, 2021–2034)
- Instruments
- Consumables
- Services
By Application Outlook (Revenue – USD Million, 2021–2034)
- Whole Genome Sequencing
- Identification & fine mapping of structural variation
- Tandem repeat sequencing
- Pseudogene discrimination
- Haplotype/Allele Phasing
- Reproductive genomics
- Cancer
- Viral & microbial sequencing
- Others
By Workflow Outlook (Revenue – USD Million, 2021–2034)
- Pre-sequencing
- Sequencing
- Data analysis
By End Use Outlook (Revenue – USD Million, 2021–2034)
- Academic research
- Clinical research
- Hospitals and clinics
- Pharma and biotech entities
- Others
By Regional Outlook (Revenue – USD Million, 2021–2034)
- North America
- U.S.
- Canada
- Europe
- Germany
- France
- UK
- Italy
- Spain
- Netherlands
- Russia
- Rest of Europe
- Asia Pacific
- China
- Japan
- India
- Malaysia
- South Korea
- Indonesia
- Australia
- Vietnam
- Rest of Asia Pacific
- Middle East & Africa
- Saudi Arabia
- UAE
- Israel
- South Africa
- Rest of the Middle East & Africa
- Latin America
- Mexico
- Brazil
- Argentina
- Rest of Latin America
Long Read Sequencing Market Report Scope
| Report Attributes | Details |
| Market size in 2025 | USD 612.34 million |
| Market size in 2026 | USD 750.35 million |
| Revenue forecast in 2034 | USD 3,868.04 million |
| CAGR | 22.7% from 2026 – 2034 |
| Base year | 2025 |
| Historical data | 2021 – 2024 |
| Forecast period | 2026 – 2034 |
| Quantitative units | Revenue in USD million and CAGR from 2026 to 2034 |
| Segments Covered |
|
| Regional scope |
|
| Customization | Report customization as per your requirements with respect to countries, region, and segmentation |
Source: Polaris Market Research Analysis
Long Read Sequencing Market FAQ's
The market size was USD 612.34 million in 2025 and is expected to reach USD 3,868.04 million by 2034.
The long read sequencing market is growing at a CAGR of 22.7% during the forecast period.
North America dominated the market with a 51.9% share in 2025.
Nanopore sequencing dominated the market with a 56.3% share in 2025.
Long-read sequencing reads longer DNA fragments, helping detect complex genetic changes, while short-read sequencing analyzes smaller fragments.
PacBio and Oxford Nanopore Technologies are key players, supported by Illumina, MGI Tech, and specialized sequencing service providers.
Yes, certain long-read platforms can detect DNA methylation directly, helping researchers study gene regulation without separate chemical treatment.
It detects complex genetic variations, repeat expansions, and structural changes that may be missed by conventional sequencing methods.
Download Sample Report of Long Read Sequencing Market
Please fill out the form to request a customized copy of the research report.